VI // TIẾNG VIỆT
VRAMFORGE // DETERMINISTIC GGUF, KV-CACHE & ROOFLINE WORKBENCH

Size Exact GGUF Tensor Weights, Parallel KV-Cache & GPU/DDR5 Bandwidth on VRAMForge

We model exact llama.cpp K-quant super-block weights (4.85–16.0 bpw), multi-stream GQA KV-cache expansion (4K–64K tokens), Qdrant HNSW overhead, and a 13% Linux OOM guard for DeepSeek-R1, Qwen-Coder, Llama 3.3, Dify, and n8n.

01 // PARAMETER PROFILE & RAG STACK (VRAMFORGE)
02 // GGUF QUANTIZATION PRECISION (EFFECTIVE BPW)
03 // CONTEXT WINDOW: 8K (8192 tok)
4K8K16K32K64K
04 // PARALLEL STREAMS: 4 concurrent streams
1x4x8x16x

VRAMFORGE LIVE MEMORY & ROOFLINE VERDICT

7B • Q4_K_M • 8K • 4x
REQUIRED FOOTPRINT
10.6 GBSnapped tier: 16 GB DDR5
ROOFLINE SPEED
~17 tok/sCPU: 17 • GPU: 147.6 tok/s
VS OPENAI API BILL
Save $568/moAPI ~$578/mo (137.7M tok)
1. GGUF Super-Block Tensor Weights ((B * BPW / 8) * 1.06)4.9 GB
2. Parallel GQA KV-Cache Buffer (Ctx * Users * Scale)2.2 GB
3. Runtime & Qdrant HNSW Vector Overhead2.1 GB
4. 13% Linux Kernel OOM Safety Margin1.4 GB
Total Footprint & Snapped Tier10.6 GB -> 16 GB
VRAMForge Generated Ollama Environment Flags
# VRAMForge generated Ollama systemd override (7B / Q4_K_M / 8K / 4 streams)
OLLAMA_FLASH_ATTENTION=1 OLLAMA_KV_CACHE_TYPE=q8_0 OLLAMA_NUM_PARALLEL=4 \
OLLAMA_CONTEXT_LENGTH=8192 ollama run deepseek-r1:7b
  • BEST ROI #1 • 1-CLICK OLLAMA DOCKER 17 tok/s (CPU AVX-512)
    Hostinger KVM 4 (16GB DDR5) $10.49/mo

    Fits 10.6 GB footprint inside 16 GB DDR5 ECC with 1-Click Ollama, Open WebUI & n8n templates + Extra 20% Partner Discount.

    Provision Hostinger via VRAMForge →
  • LOW-LATENCY GPU ACCELERATOR 147.6 tok/s (NVIDIA VRAM)
    Vultr NVIDIA A16 (16GB VRAM) $185.00/mo

    Upgrades generation speed to ~147.6 tok/s via dedicated GDDR6 VRAM in Singapore & Tokyo with hourly billing.

    Provision Vultr Cloud GPU via VRAMForge →
  • LIFETIME PRICE-LOCK GUARANTEE 17.9 tok/s (Ryzen/KVM)
    InterServer KVM 16GB Price-Lock $24.00/mo

    Zero renewal price hikes ever — predictable long-term private AI hosting with high NVMe storage headroom.

    Provision InterServer via VRAMForge →

VRAMForge Silicon Decision Lanes: DDR5 KVM vs Dedicated VDS vs Cloud GPU

We separate self-hosted LLM infrastructure into three deterministic bandwidth lanes so you neither starve RAM nor overpay for idle Tensor Cores.

LANE 01 // 8 GB – 32 GB DDR5 KVM

Hostinger DDR5 KVM for 7B–14B & n8n on VRAMForge

Built for 1–4 internal users, n8n/Flowise background agents, and Qdrant under 2M vectors.

Sustained Bandwidth
~78 – 95 GB/s AMD EPYC DDR5 (12–20 tok/s @ 8B Q4_K_M)
OOM Ceiling
Max 14B Q5_K_M (16K ctx) inside 32 GB KVM 8
Inspect Hostinger KVM via VRAMForge →
LANE 02 // 64 GB – 128 GB DEDICATED VDS

UltaHost Dedicated VDS for 32B/70B & Dify on VRAMForge

Dedicated physical cores prevent hypervisor CPU steal during 60s DeepSeek-R1 reasoning chains and 9-container Dify stacks.

Sustained Bandwidth
~115 – 135 GB/s Dedicated DDR5 ECC (Zero CPU Steal)
OOM Ceiling
32B Q8_0 or 70B Q4_K_M + Qdrant inside 64–128 GB VDS
Inspect UltaHost VDS via VRAMForge →
LANE 03 // 16 GB – 80 GB GDDR6 / HBM2E

Vultr NVIDIA Cloud GPU for Live vLLM & FIM on VRAMForge

Mandatory when IDE tab-autocomplete demands <300ms TTFT or 8–16 concurrent users query 32K RAG contexts.

Sustained Bandwidth
600 – 1,555 GB/s NVIDIA A16 / L40S / A100 Tensor Cores
OOM Ceiling
vLLM PagedAttention continuous batching (40–120+ tok/s)
Inspect Vultr Cloud GPU via VRAMForge →
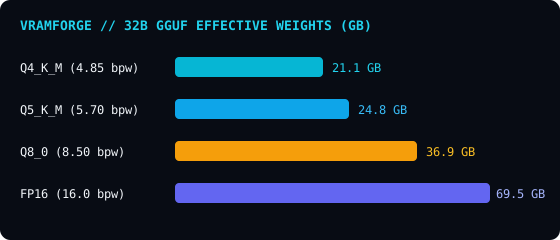
VRAMForge 32B GGUF effective bits-per-weight memory comparison chart
Figure 1 (VRAMForge): Deterministic 32B parameter weight footprint scaling from Q4_K_M (21.1 GB) to FP16 (69.5 GB).
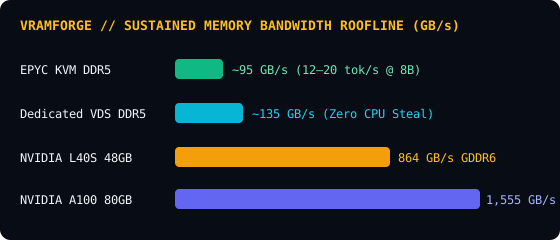
VRAMForge DDR5 KVM and VDS versus NVIDIA L40S and A100 memory bandwidth roofline chart
Figure 2 (VRAMForge): Memory-bandwidth ceiling governing autoregressive tok/s across DDR5 VPS/VDS and NVIDIA GPUs.
VRAMFORGE 15S VERTICAL BRIEFING (9:16 HD MP4)

VRAMForge Video Briefing: Prevent OOM Kills & Per-Token API Leakage

We walk through how VRAMForge sizes 7B to 70B Q4_K_M and Q8_0 weights plus multi-user RAG context windows before provisioning fixed-rate DDR5 VDS or Cloud GPU capacity.

VRAMForge GGUF Quantization Footprint Matrix (4.85 – 16.0 BPW at 8K / 4x)

Deterministic total memory lookup (including 4-stream 8K KV-cache and 13% OOM margin) across five model classes.

Model / RAG Profile Q4_K_M (4.85 bpw) Q5_K_M (5.70 bpw) Q8_0 (8.50 bpw) FP16 (16.0 bpw)
7B – 8B LLM 10.6 GB (16 GB) 11.7 GB (16 GB) 15.5 GB (16 GB) 25.5 GB (32 GB VRAM)
14B LLM 17 GB (24 GB) 19.3 GB (24 GB) 26.3 GB (32 GB) 45.4 GB (48 GB VRAM)
32B LLM 31.2 GB (32 GB) 36 GB (48 GB) 50.7 GB (64 GB) 91 GB (96 GB VRAM)
70B Frontier 60.1 GB (64 GB) 69.8 GB (96 GB) 100.8 GB (128 GB) 184.3 GB (192 GB VRAM)
RAG + Open WebUI + Qdrant 19.5 GB (24 GB) 21 GB (24 GB) 25.5 GB (32 GB) 37.9 GB (48 GB VRAM)

VRAMForge Public Vendor Tariff & Silicon Spec Reference (Retrieved 2026-11-12)

Source citation: Compiled from publicly listed vendor pricing schedules retrieved on 2026-11-12. Promotional introductory rates, free GPU credits, and renewal prices can change at any time — always confirm current terms on the vendor checkout page.

Vendor & Official Pricing Source Memory / VRAM Envelope Compute / Tensor Architecture Published Entry Rate (2026-11-12) VRAMForge Partner Route
Hostinger
https://www.hostinger.com/vps-hosting
4 GB – 32 GB DDR5 ECC RAM AMD EPYC AVX-512 KVM (1 – 8 vCPU) $4.99/mo (2026-11-12) Open Hostinger via VRAMForge →
UltaHost
https://ultahost.com/vds-hosting
32 GB – 192 GB Dedicated DDR5 ECC Dedicated Physical EPYC Cores (100% Sustained AVX-512) $37.5/mo (2026-11-12) Open UltaHost via VRAMForge →
Vultr
https://www.vultr.com/pricing/
16 GB – 80 GB GDDR6/HBM2e VRAM + Up to 256 GB RAM NVIDIA A16, L40S (48GB), A100 (80GB) & 3.5GHz+ HF Compute $24/mo (2026-11-12) Open Vultr via VRAMForge →
InterServer
https://www.interserver.net/vps/
16 GB – 128 GB Dual-Channel DDR5 AMD Ryzen 7900/5950X Bare-Metal & KVM Slices $12/mo (2026-11-12) Open InterServer via VRAMForge →
ChemiCloud
https://chemicloud.com/wordpress-hosting
2 GB – 6 GB Managed Web LiteSpeed Enterprise NVMe Edge $2.95/mo (2026-11-12) Open ChemiCloud via VRAMForge →

VRAMForge Self-Hosted AI Blueprints & Infrastructure TCO Index

Jump straight into container compose manifests, KV-cache flags, and 12-month API break-even equations.

VRAMForge GGUF Quantization & Roofline Sizing Q&A